The baseline has declined to cooperate
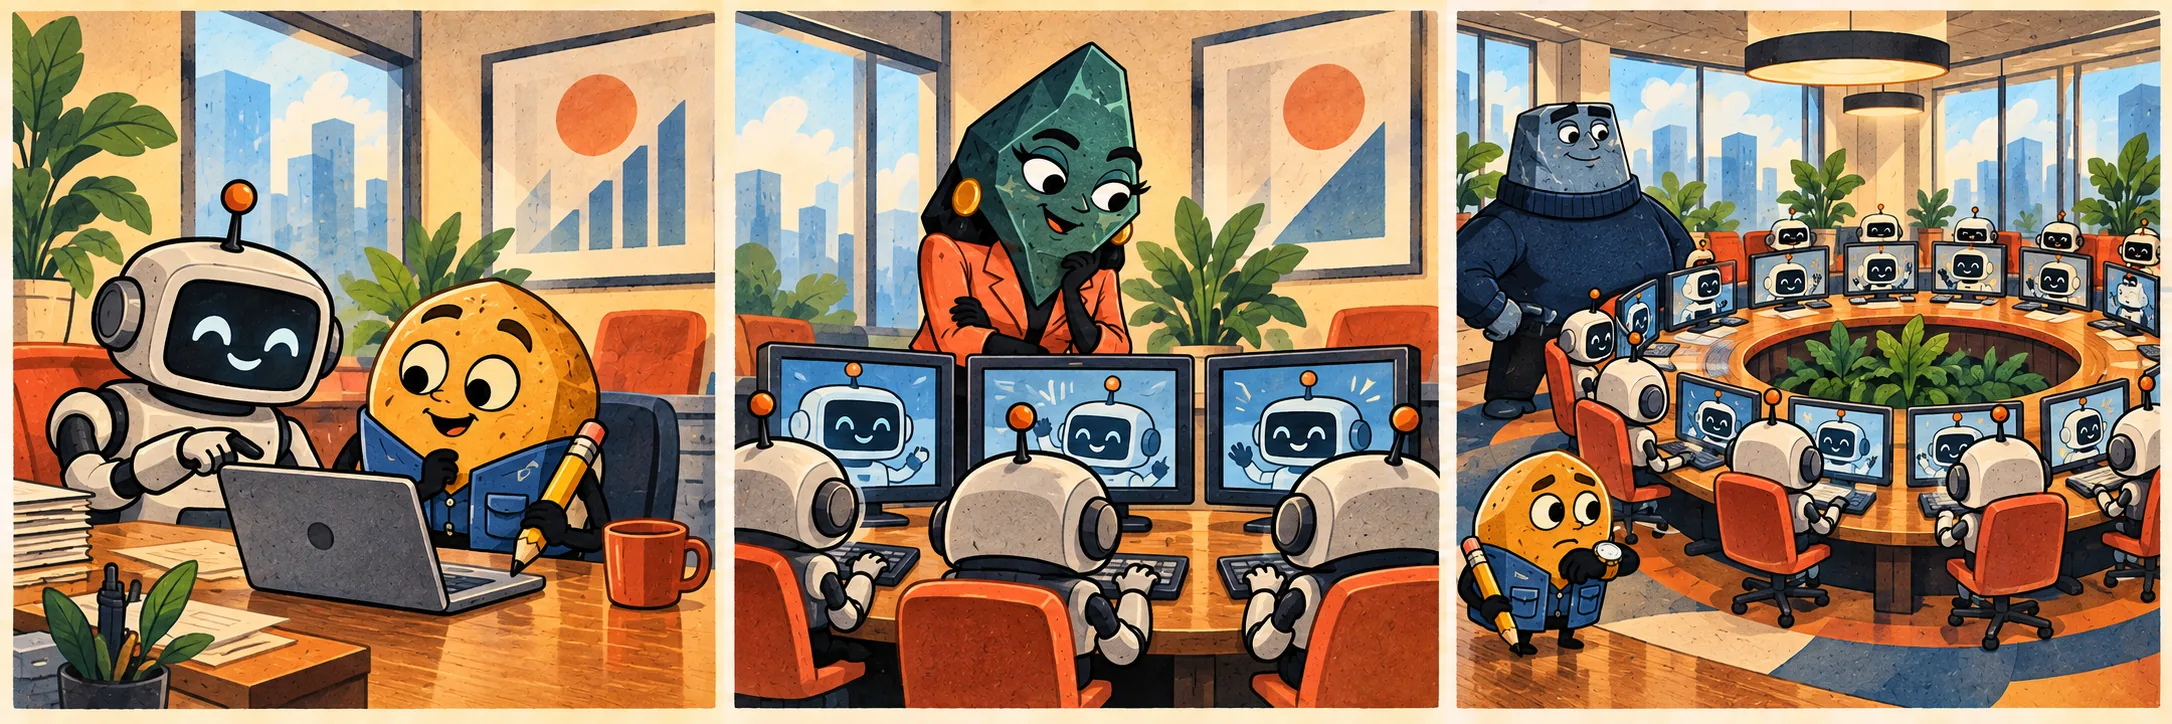
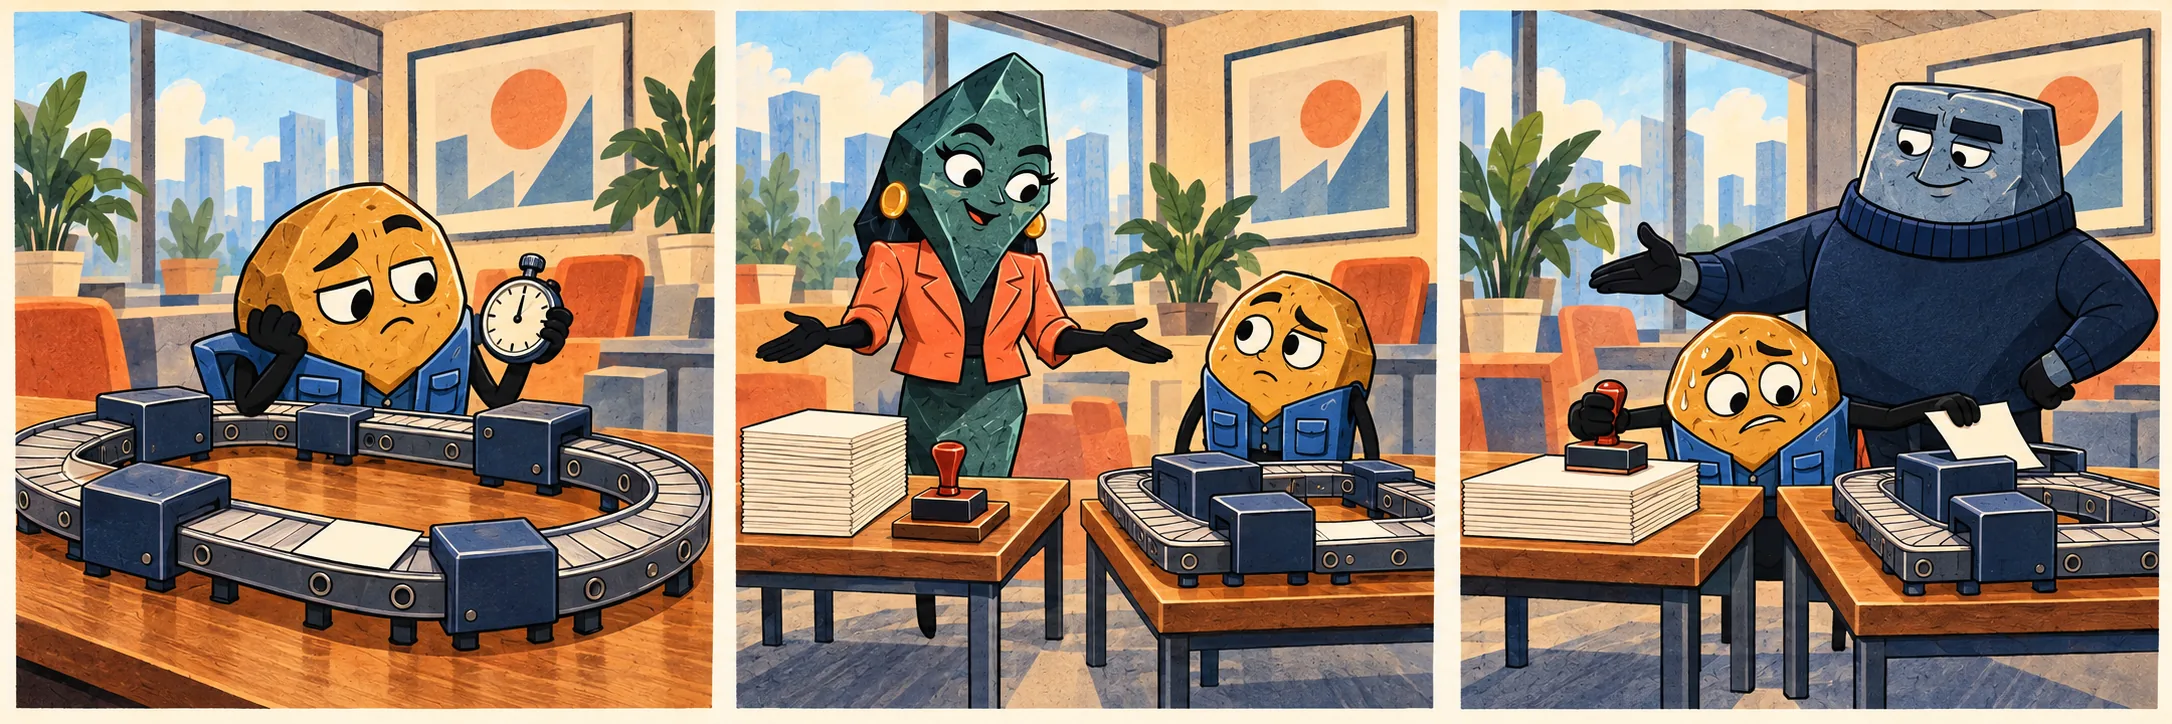
Chip volunteered to establish the manual baseline. He completed the task, checked it and sent it to the person who needed it. This was disappointing. He had neither opened a transformation ticket nor attended the workshop explaining why his task required transformation. We could not find a place for the result in the programme.
Our automated version involves a drafting agent, a checking agent and an agent that reconciles their disagreement. Chip reviews the output because he remains the person expected to explain it to the customer. We have retained his original task as a control, so he now performs it twice. The programme records this as exceptional employee engagement.
The machine finishes its part impressively quickly. Unfortunately, its part ends just before somebody has to decide whether the work is correct. We considered extending the stopwatch through review and rework, but this would make the graph less suitable for the board pack. Finance has offered to crop it.
A complete result is an awkward unit of measurement
There is a useful test beneath this administrative inconvenience. Choose a defined job, hold the acceptance criteria steady, and include the human effort needed to produce an acceptable result. A faster first draft may still be valuable. It does not become a finished job merely because the remaining work belongs to somebody on a different cost centre.
THE FIRM’S WORKING MODEL
Two ways our firm can assess the same workflow
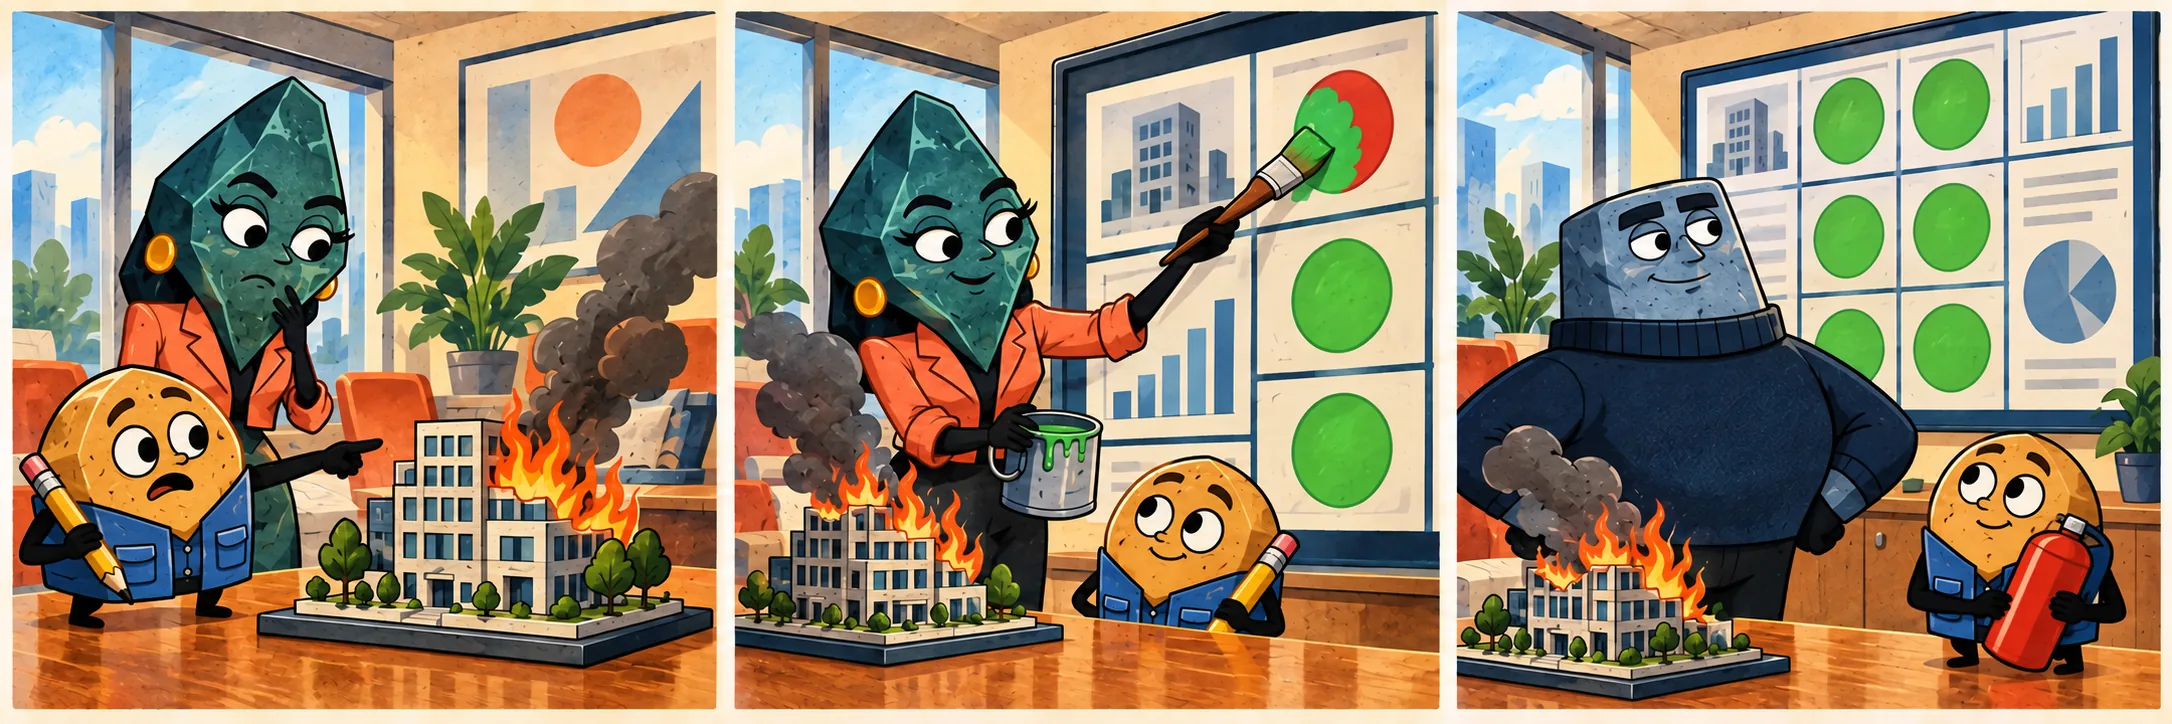
Count available digital workers. Keep the unfinished job off the slide.
Include machine time, human review and rework. Compare like-for-like jobs.
This also requires allowing a test to fail. If the manual process wins, the sensible response is to investigate the workflow or remove the unnecessary automation. Our response is to promote the workflow to a more strategic category, where ordinary comparisons become culturally insensitive. Chip has requested permission to use the old method while we investigate. We have requested that he stop calling it the working one.
Savings must remain available for future engagements
A provider can earn money installing agents while a customer hopes to spend less getting work done. Those interests can align, but a growing installation list does not demonstrate that they have. Somebody needs authority to reject an impressive deployment that produces an unimpressive result. At SoftBoulders, this authority belongs to the sponsor, provided the sponsor can be located after the launch photograph.
We have therefore adopted a balanced scorecard. Leadership receives the digital headcount. Delivery keeps the stopwatch. Both departments report excellent progress because we have cancelled the meeting where they compare notes.
Chip's control task remains on his desk. We cannot retire it yet. It is the only part of the experiment that consistently produces the thing we are measuring.
Behind the brief: IBM Consulting and productivity measurement
In an interview first published by The Financial Express on October 18, IBM Consulting leader Mohamad Ali described roughly 6,000 agents integrated into more than 150 workflows. He said IBM tests workflows with and without agents in its Bengaluru productivity lab, and acknowledged that some deployments reduce productivity. These are attributed statements from the interview, not independent measurements by SoftBoulders. The census, control-task experiment and management policies above are SoftBoulders’ own comic response.
- The Financial Express: IBM Consulting describes agent deployment and tests of workflow productivity Oct 18, 2026
News date: Oct 18, 2026. Article published: Oct 19, 2026. The policies and proposals in this article are SoftBoulders’ comic response; the linked sources describe the underlying events. Editorial notes.